Physical AI Data Annotation
Annotation for robot learning, embodied agents and egocentric & exocentric video - from spatial and temporal labels to robot action and language, delivered by expert human-in-the-loop teams.

What Is Physical AI Data Annotation?
Physical AI covers the models that have to act in the world, not just describe it: robot learning, embodied agents and human activity understanding. The datasets that train them need a layered annotation stack - spatial labels on frames, temporal labels on sequences, view-specific labels for egocentric and exocentric footage, and action and language labels that tie video to robot control.
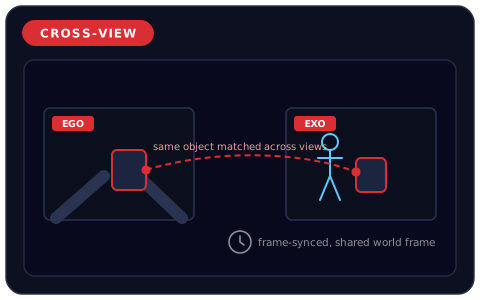
Egocentric (first-person) footage carries fine hand and object detail and intent; exocentric (third-person) footage carries full-body pose and spatial context. Physical AI datasets are strongest when both are captured together, time-synced, and labeled with matching cross-view annotations.
HaiData annotates all of these layers with expert human-in-the-loop teams. Need the raw footage too? See our egocentric data collection services, or read our primer on egocentric vs exocentric datasets.

Physical AI Annotation Use Cases
The annotation behind the models that have to move, manipulate and understand real environments.
Robot Learning & Imitation
Annotate human and teleop demonstrations so manipulation policies can learn what a task looks like, step by step, from the actor's own point of view.
Vision-Language-Action (VLA)
Pair demonstration episodes with per-step language instructions so vision-language-action models can ground words in states, actions and outcomes.
Embodied AI & World Models
Label first-person video with motion, contact and state changes so world models learn how actions change the scene around an agent.
Human Activity Understanding
Action segments, keysteps and object state changes turn long-horizon tasks - cooking, assembly, repair - into supervised sequences.
AR/VR Assistants
Gaze, hand-object interaction and mistake tagging give first-person assistants the grounding to guide a wearer through a task in context.
Skill & Proficiency Assessment
Expert-vs-novice and proficiency labels, paired across egocentric and exocentric views, support technique, posture and quality analysis.

Annotation Layers We Deliver
A layered stack for Physical AI datasets - spatial and temporal labels, view-specific labels for ego and exo footage, cross-view links, and the robot action and language layer that ties video to control.
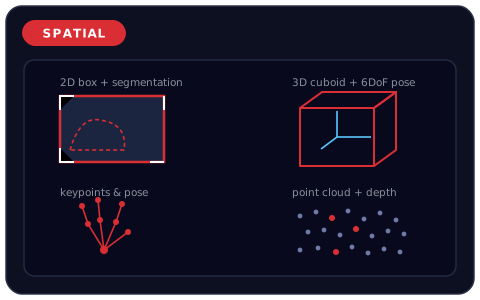
Spatial Annotation
2D boxes, polygons and semantic, instance and panoptic segmentation of objects, tools, hands and surfaces; 3D cuboids and 6DoF object pose aligned to CAD or meshes; 21-keypoint hand pose and full-body pose (COCO, SMPL/SMPL-X); depth, point clouds, surface normals and camera pose and calibration.
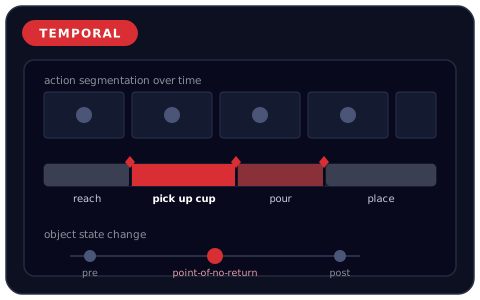
Temporal Annotation
Action segmentation with start/end timestamps and verb-noun labels; keystep and procedural-step labels for long-horizon tasks; object state change (pre-state, point-of-no-return, post-state); anticipation labels; mistake and deviation tagging; and dense timestamped natural-language narrations.
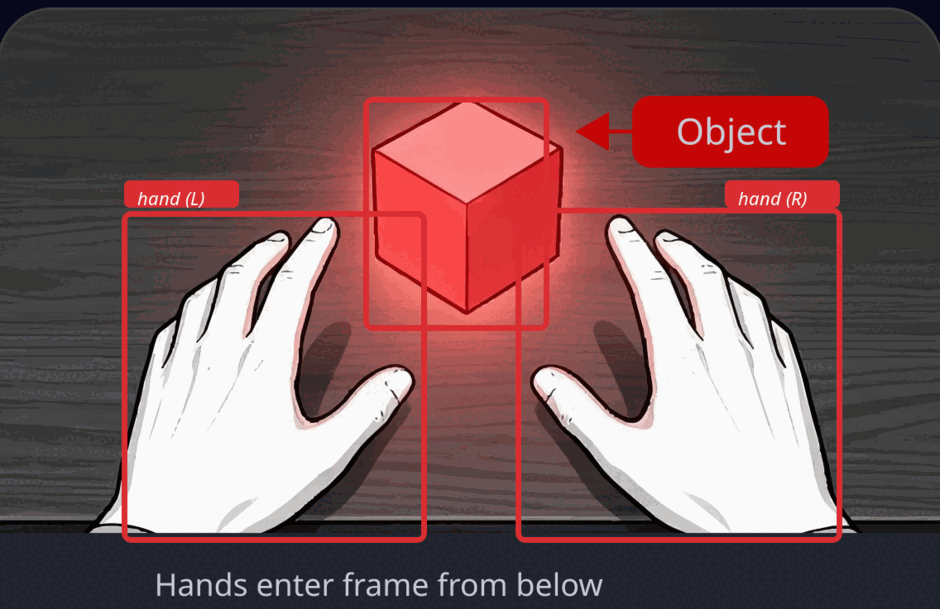
Egocentric-Specific
Hand-object interaction (hand boxes and masks, left/right, contact vs no-contact, active object); gaze and attention; egomotion and head-motion compensation; episodic-memory and visual-object queries; audio-visual labels (wearer vs bystander, diarization, transcription); proficiency; and privacy de-identification.
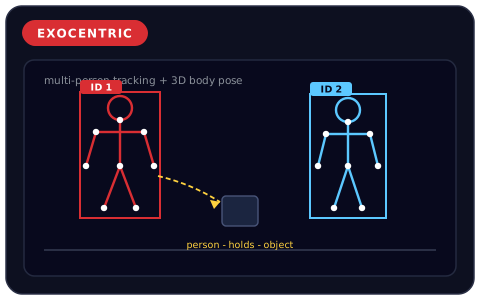
Exocentric-Specific
Multi-person detection, tracking and re-identification across cameras; 3D full-body pose and mesh recovery with mocap-to-video alignment; human-object interaction triplets and scene graphs with spatial relations; environment mapping (floor plans, traversable areas, obstacles, semantic zones); and group and social activity labels.
Cross-View (Paired Ego-Exo)
Frame-level temporal sync across all cameras; cross-view correspondence that matches the same object, hand or point between egocentric and exocentric frames; wearer identification in the exo views; and a shared world coordinate frame for every sensor.
Robot Action & Language (VLA)
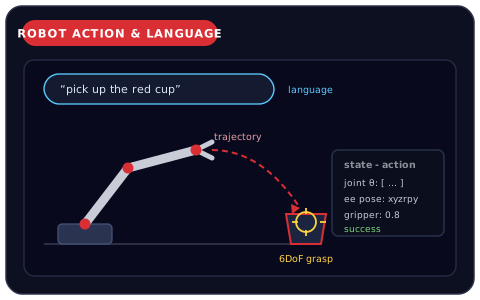
Demonstration episodes as timestamped state-action pairs (joint angles, end-effector pose, gripper state); per-episode and per-subtask language instructions for vision-language-action (VLA) training; grasp annotation (points, grasp-type taxonomy, 6DoF poses); contact and force events; affordance labels; episode quality (success, failure, safety events); and scene VQA pairs.
How HaiData Annotates Physical AI Data
Physical AI annotation is an operations problem as much as a labeling one: many layers, many sensors, and a quality bar that a single unchecked pass cannot meet. We run every project through domain-trained human-in-the-loop teams with multi-level and automated quality control, so each layer is reviewed against your acceptance criteria before delivery.
We annotate to your schema and to industry-standard formats - Ego4D-style narrations, Open X-Embodiment and DROID-style demonstration episodes, COCO and SMPL/SMPL-X pose - and deliver labeled data securely to your own cloud. Data handling is GDPR-aligned and aligned with India's DPDP Act 2023, with de-identification built into sensitive projects.
Explore our broader data annotation services and 3D point cloud annotation.
Why HaiData for Physical AI Annotation
Ethics, quality and control, built into every layer we label.
Domain-Expert HITL Teams
Trained human-in-the-loop annotators who understand robotics, embodied AI and first-person data, not a generic crowd guessing at hand-object contact or grasp poses.
Ego, Exo & Robot in One Place
Spatial, temporal, egocentric, exocentric, cross-view and robot action and language labels from a single partner, so your layers stay consistent and aligned.
Multi-Level & Automated QC
Every layer passes multiple levels of human review plus automated checks with configurable acceptance thresholds, so only labels that meet your bar are delivered.
Consent-First & Private
De-identification such as face, screen and document blurring, GDPR-aligned handling and alignment with India's DPDP Act 2023. ISO 27001 is in progress, expected 2026.
Format-Flexible
We annotate to your schema and to standard formats - Ego4D, Open X-Embodiment, DROID, COCO, SMPL/SMPL-X - so labeled data drops into your pipeline.
Secure Own-Cloud Delivery
Labeled datasets are delivered to your own cloud storage in the region you choose, with clear provenance and documented quality throughout.
Industries we Serve
AI is industry agnostic. So do we!

Automotive

Healthcare

Agri Tech

Retail

Warehousing
And More...
Related Services
Physical AI annotation pairs naturally with the rest of our stack. Explore our egocentric data collection services, human-in-the-loop services, 3D point cloud annotation, image and video annotation, and our full data annotation services.
Frequently Asked Questions
Ready to Annotate Your Physical AI Datasets?
Tell us your layers, formats and volumes and we will scope a Physical AI annotation project - egocentric, exocentric, cross-view and robot action and language. Write to us at info@haidata.ai to get started.
Contact UsGet in touch
For support and query:
Email us at info@haidata.ai
Ainnotate Data Technologies LLP
Prestige Tranquilty,
Budigere Cross,
Bangalore - 560049
Karnataka, India.
Sree Nagammal Bldg.
Manjoor,
The Nilgiris - 643219,
Tamil Nadu, India.

© 2026 | All Rights Reserved | Privacy Policy
HaiData is an AI Data solutions and services organization catering to the AI data needs of various industries. Started with the objective of contributing to "Data Centric AI", HaiData has invested in all aspects of the AI Data value chain - including services, technology and solutions. As an organization committed to providing jobs for technically qualified youth, who chose to work from rural places rather than cities, HaiData provides affordable AI Data related solutions and services to organizations across the world from the villages of Nilgiris hills, in India.